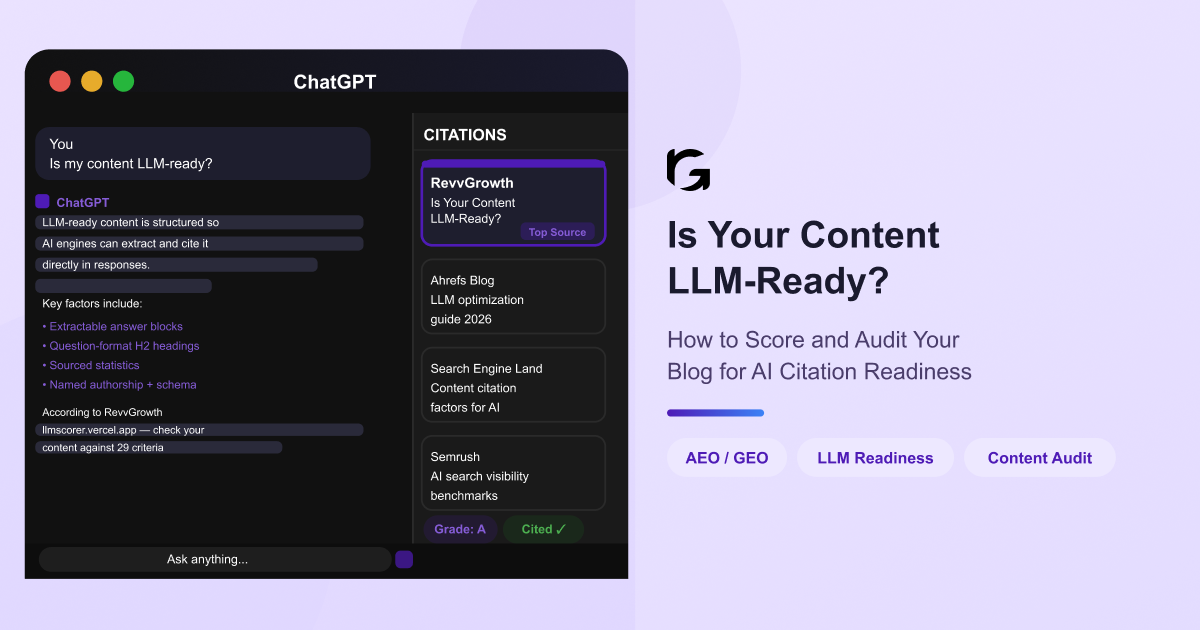
- LLM readiness is different from SEO: Google ranks pages, AI engines extract answers, and 28.3% of pages ChatGPT cites have zero Google presence at all.
- Content is scored on 6 dimensions: extractability, authority, relevance, freshness, access, and repetition, weighted across 29 criteria.
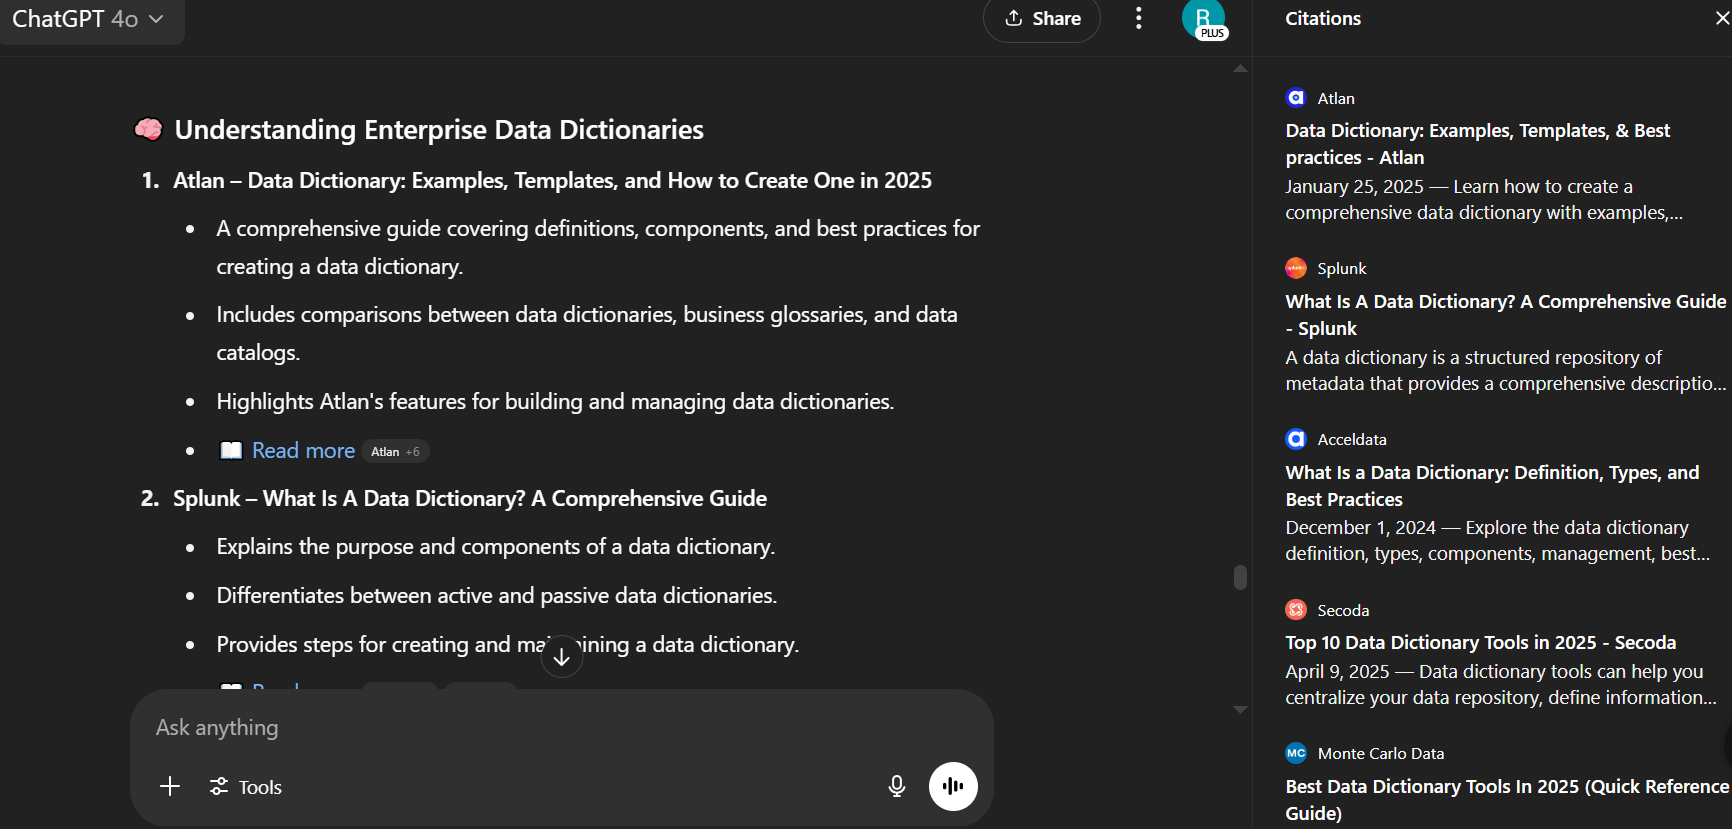
- Real results: OvalEdge went from 2,130 to 8,200 organic clicks in 5 months; Atlan is ChatGPT's #1 cited source for "enterprise data dictionaries," above Wikipedia.
- Fixing existing content beats publishing more: a 6-step retrofit (answer capsules, question headings, sourced stats, schema, authorship) moves most Grade C pages to Grade B within a week.
"Why does my competitor show up when I ask ChatGPT about our category and we don't?"
We get this on almost every first call. The team has published consistently. They rank on Google. Their content is genuinely better than what is being cited. And yet, nothing.
The answer is rarely content quality. It is the content structure.
LLM content readiness is how well your content is built for AI engines, ChatGPT, Perplexity, and Google AI Overviews to extract, trust, and cite it in responses. Unstructured, statistic-light, answer-absent content will not get cited regardless of how well it ranks on Google.
According to Semrush's 2026 research, AI-referred visitors convert at 4–5× the rate of traditional organic traffic. If you have not optimized content for AI search, you are not just missing traffic. You are missing a pipeline.
Most SaaS content teams are still writing for their own website. That is the problem. AirOps research found that 85% of brand mentions in AI responses came from third-party pages, not the brand's own domain. Your on-site content strategy alone will never be enough. LLM readiness requires a different approach entirely, and most content libraries are not built for it.
This guide gives you the framework to close that gap with the six dimensions LLMs score your content on, a five-step audit process you can run today, and exact remediation steps for every failure grade.
But do this before reading further.
Paste your best-performing blog URL into the LLM Scorer. It checks your content against 29 citation-readiness criteria, gives you an A–D grade, flags critical failures, and tells you exactly what to fix, in 60 seconds.
Then come back. Every section of this guide maps directly to what your score surfaces.
What Does "LLM-Ready" Actually Mean?
LLM-ready content is structured so that an AI engine can find it, extract a specific answer from it, trust the source, and reproduce that answer in a generated response — with or without sending the user to your site. It is not about keyword density, word count, or backlink profiles. It is about extractability, answer clarity, and source credibility signals that AI systems can parse in milliseconds.
Core Elements:
Extractability — each section answers its heading question in the first two sentences, before any supporting detail follows
Answer clarity — the primary question is answered near the top of the page, not buried after a 600-word introduction
Source credibility signals — named authorship, sourced statistics, and schema markup that AI systems can verify and attribute
Is your content structured for AI citation?
Score Your Content Free →Ranking and Being Cited Are Two Separate Problems
You can rank number one on Google for a target keyword and never appear in a single ChatGPT or Perplexity response. The inverse is also true.(Ahrefs)
Ahrefs' analysis of ChatGPT's most-cited pages found that 28.3% of pages cited by ChatGPT have zero organic search presence. They rank for nothing. Google has never noticed them. And yet AI engines cite them consistently.
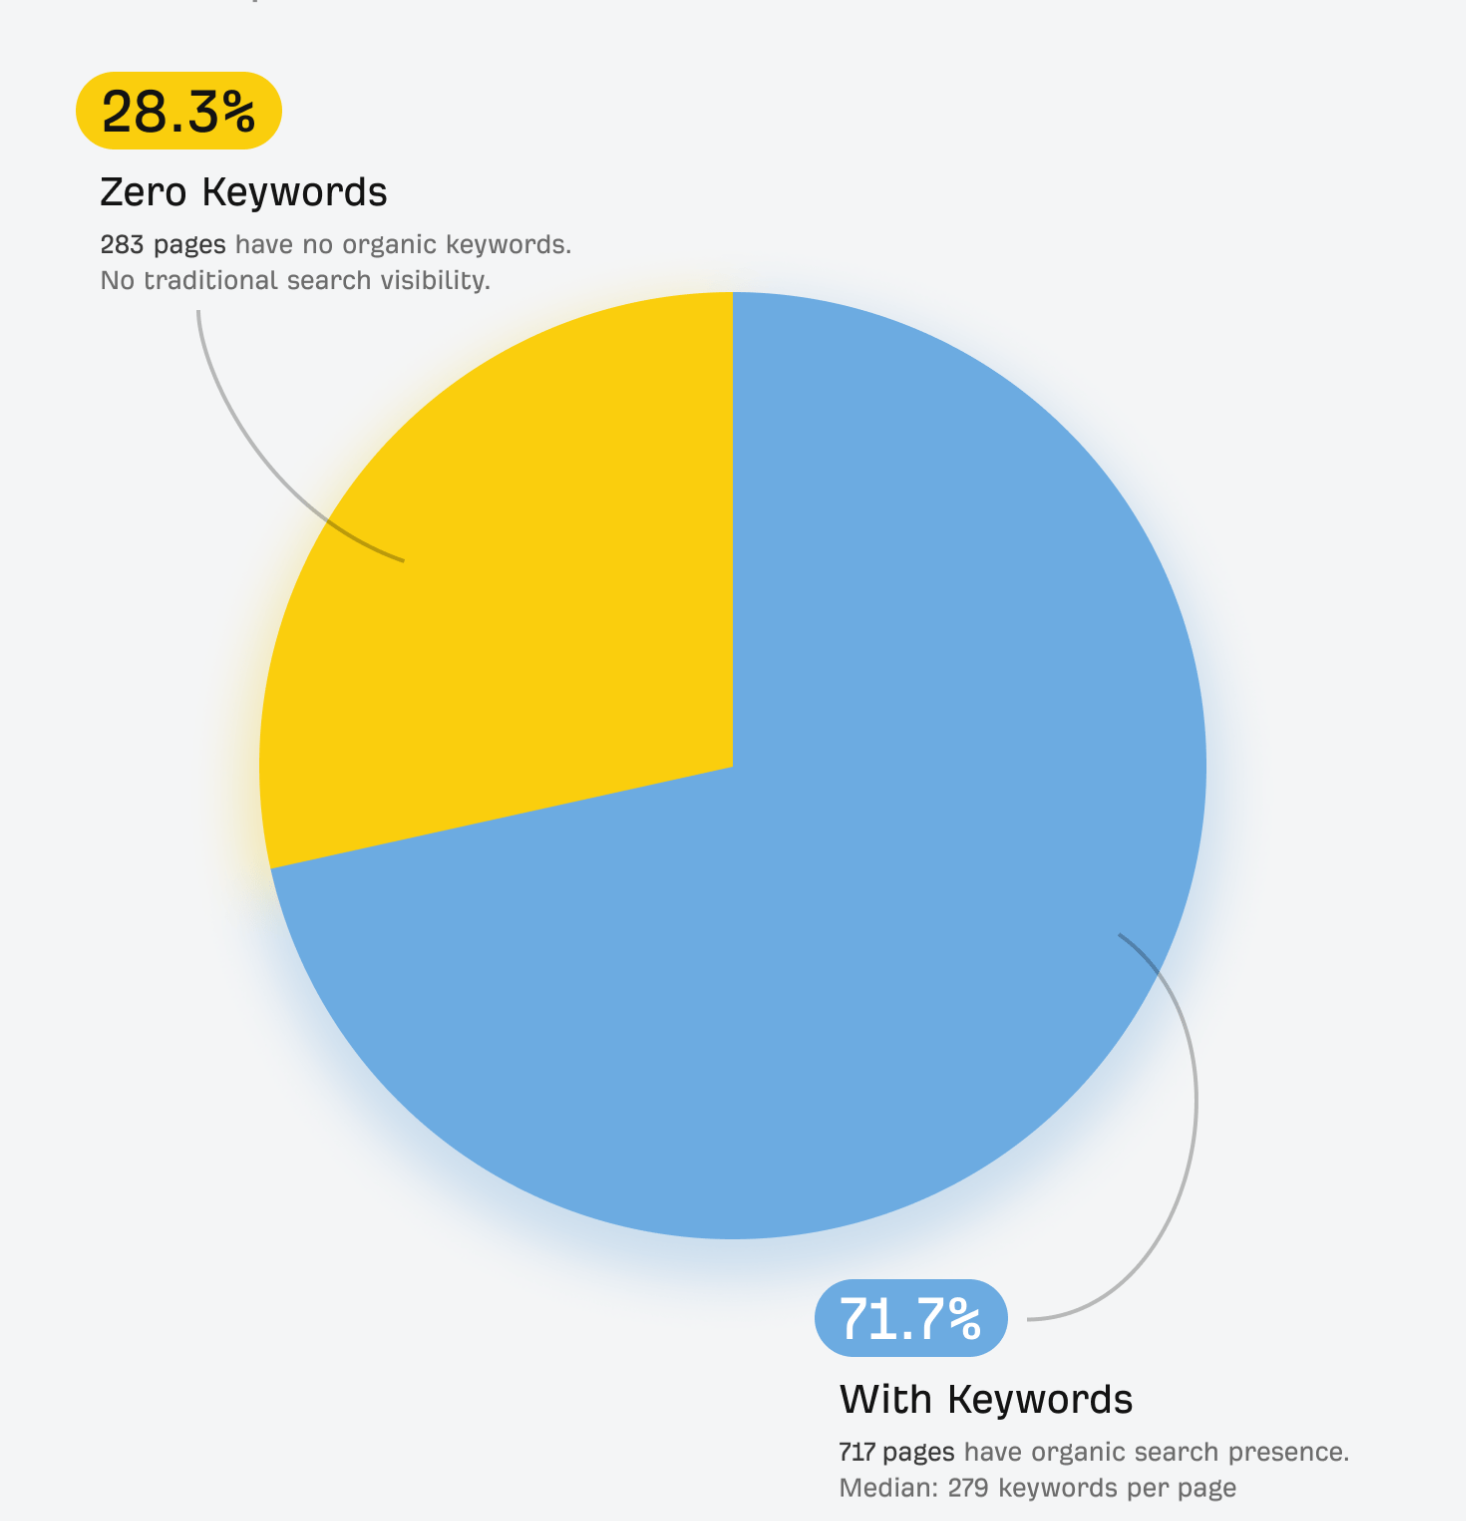
Why? Because LLMs do not rank pages. They extract answers. A page that clearly answers a specific question, in plain language, with verifiable data, in a format the model can lift directly, will be cited over a page that ranks well but buries its answer inside a 3,000-word introduction.
What LLMs Are Actually Looking For
When an LLM retrieves content to cite, it is evaluating three things simultaneously:
1. Can I extract a clean answer from this?
AI systems favour content with self-contained sections, where each H2 directly answers its own heading and the answer is complete within the first two or three sentences. Research across citation datasets found that content structured in clear 50–150 word extractable chunks receives 2.3× more citations than long-form unstructured content of equal quality.
2. Can I trust this source?
LLMs weigh authority signals differently from Google. On-site backlinks matter far less than third-party mentions, entity consistency across platforms, and the presence of verifiable, sourced data within the content itself.
The Princeton GEO study found that GEO-optimised content can boost visibility in AI-generated responses by up to 40%, with quotation addition and statistics addition among the highest-performing strategies tested.
3. Is the answer close to the surface?
According to Averi AI's 2026 research, 44.2% of all LLM citations come from the first 30% of an article's text. Content that buries its key insight at paragraph twelve, after the background, the context, and the scene-setting, is structurally invisible to AI engines, regardless of what it says.
LLM Readiness Is Not a Single Signal
This is where most audits go wrong. Teams fix one element, usually adding an FAQ section or shortening their paragraphs, and expect citation rates to improve. LLM readiness is a composite score across multiple dimensions: answer structure, statistical density, entity clarity, heading format, freshness signals, and third-party citation footprint.
That is exactly what the LLM Scorer checks: 29 criteria across six sections, weighted by their actual impact on citation probability.
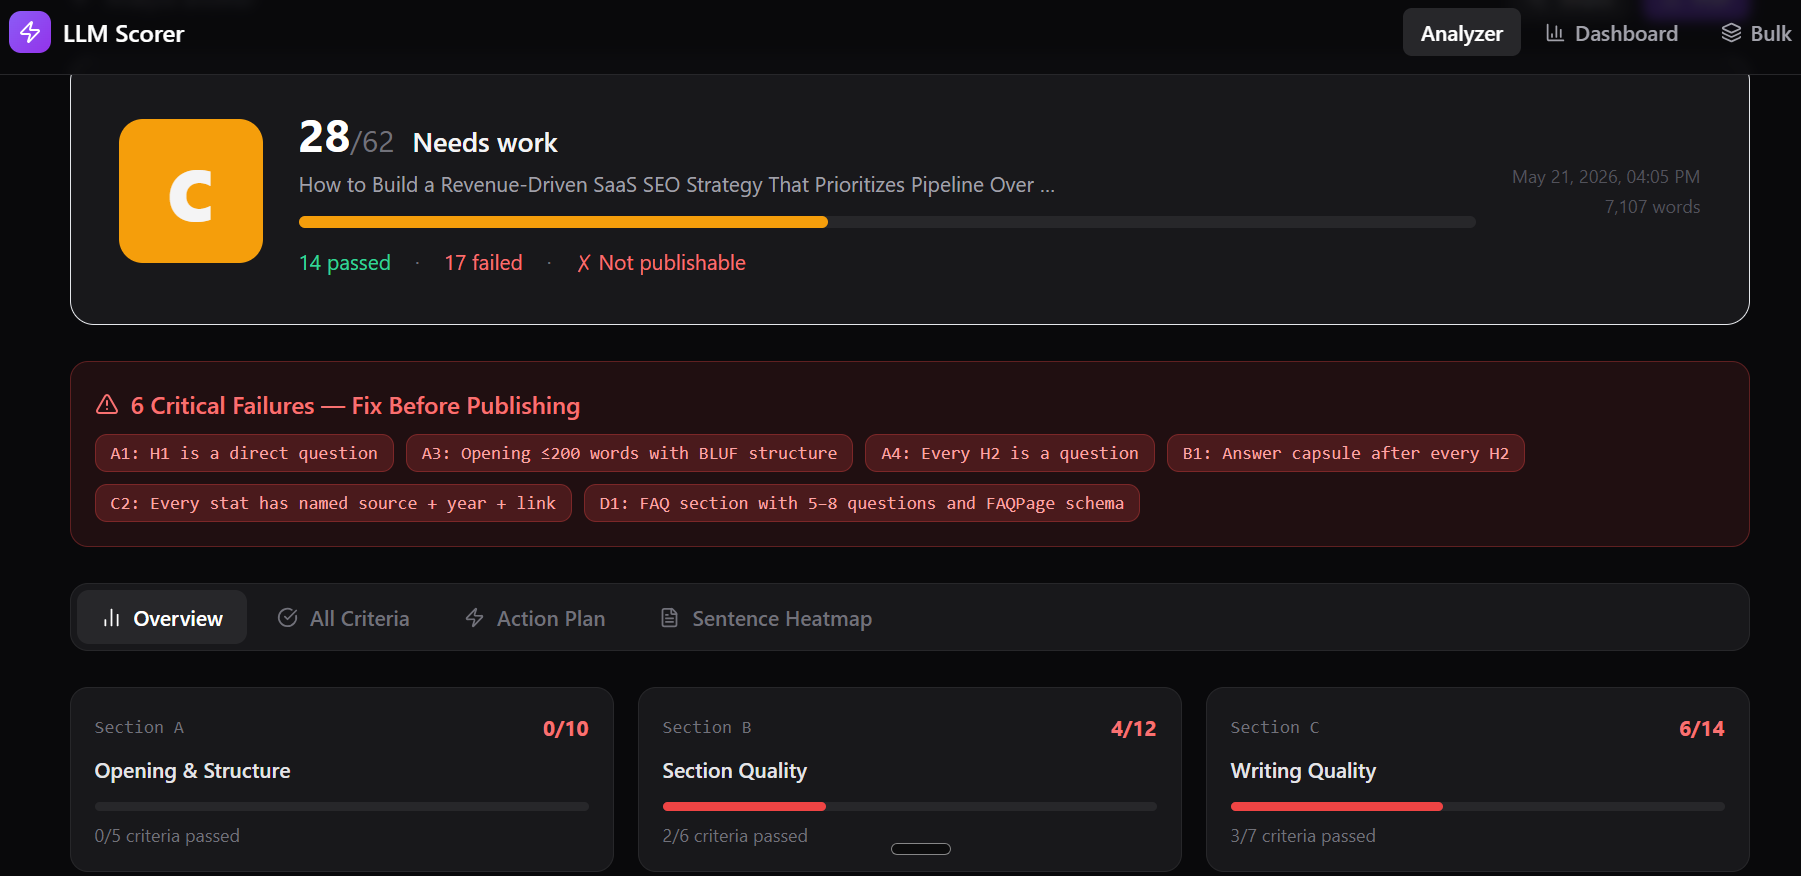
We checked one of our blogs with this scorer and found certain issues that require immediate attention, so we can fix and republish our blog. Try it now.
The 5 Specific Reasons Your SaaS Content Gets Ignored by AI
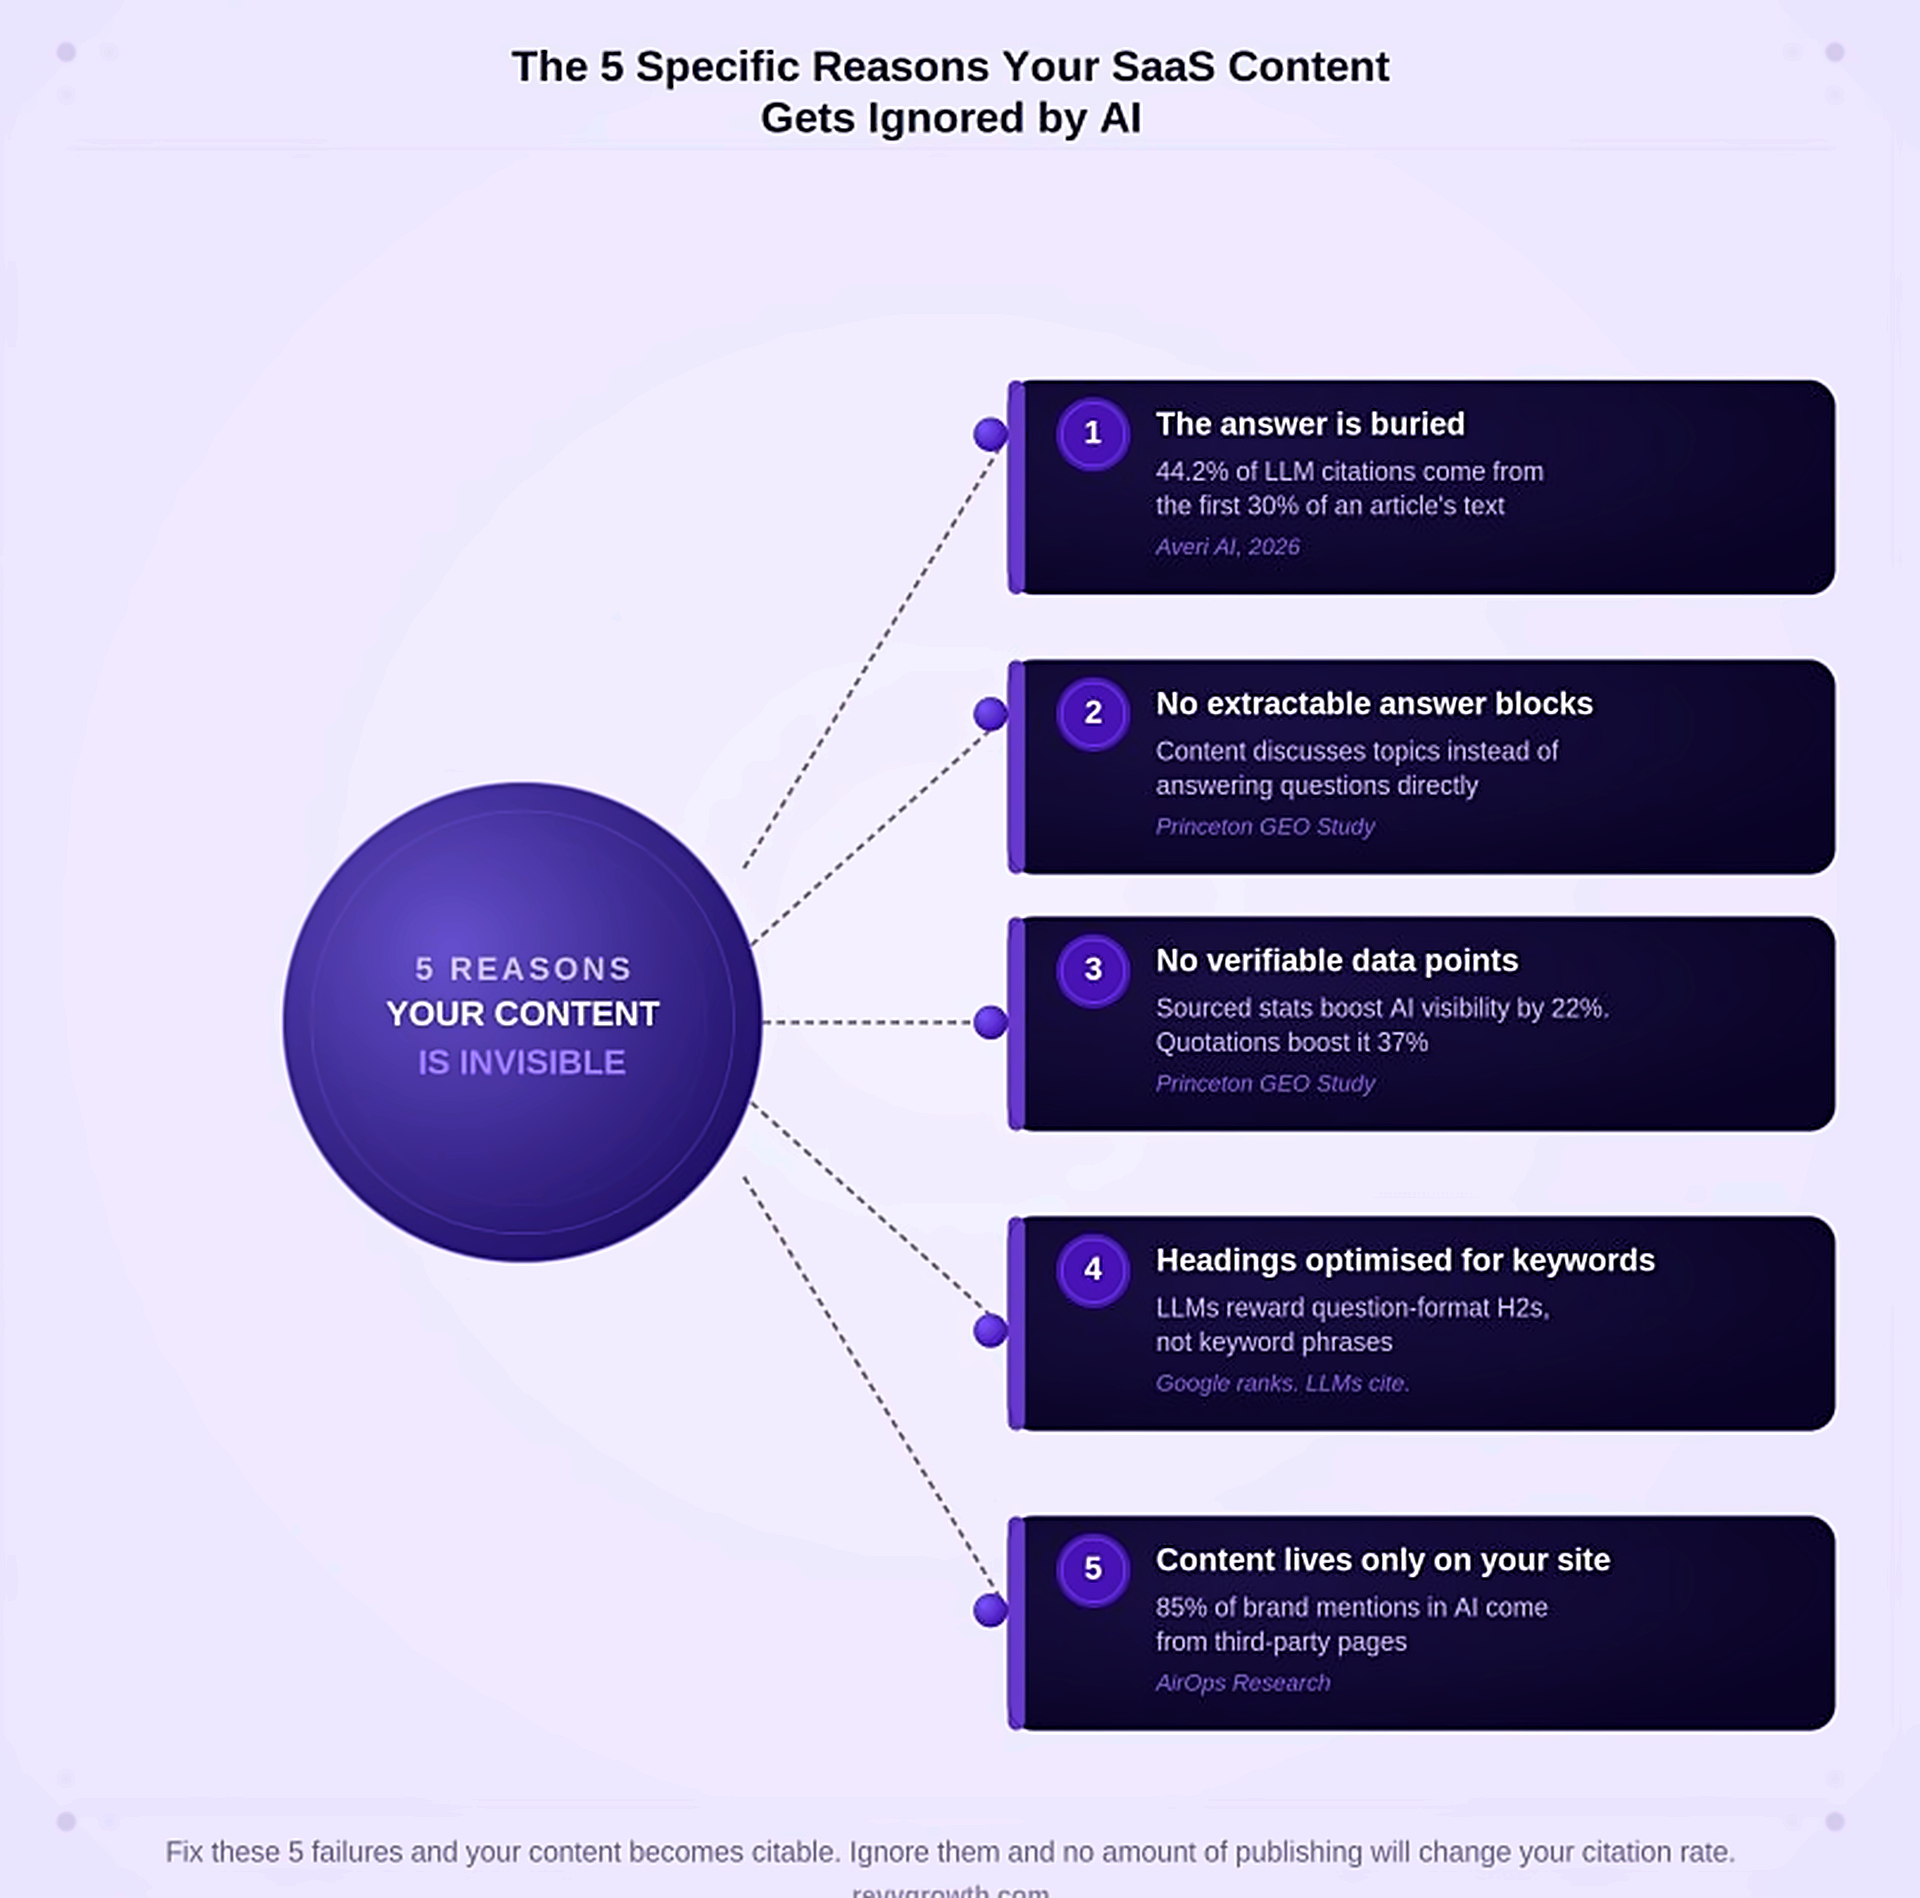
Reason 1: The answer is buried.
Most SaaS blog posts are structured like essays, context first, answer later. The background section, the market overview, and the "why this matters" preamble. By the time the actual answer appears, it is 600 words into a 2,500-word article. LLMs extract from the surface.
According to Averi AI's 2026 research, 44.2% of all LLM citations come from the first 30% of an article's text. If your answer is not near the top, it will not be cited, regardless of how good it is.
Reason 2: The content has no extractable answer blocks.
A well-optimised page for LLM citation contains what the Princeton GEO study calls "answer capsules", self-contained, 40–80 word direct responses to the exact question the section heading poses.
Most SaaS content lacks this. It has paragraphs that discuss a topic, not paragraphs that answer a question. The distinction sounds minor. The citation rate difference is not.
Reason 3: There are no verifiable data points in the content.
LLMs are designed to reproduce trustworthy information. An article that makes claims without sourcing them, "conversion rates are higher for BOFU content" rather than "BOFU content converts at 3–5% compared to 0.1–0.5% for TOFU, according to Directive's 2025 benchmarks", gives the model nothing to verify and nothing to anchor a citation to.
The Princeton GEO study found that adding sourced statistics to content increases AI visibility by 22%. Sourced quotations increase it by 37%. Unsourced claims increase it by nothing.
Reason 4: The headings are optimised for keywords, not questions.
Google rewards keyword-rich headings. LLMs reward question-format headings, because the model can match a user's query directly to an H2 that poses the same question and extract the answer from the paragraph below it.
"Revenue Intelligence Software Features" is a keyword heading. "What features should you look for in revenue intelligence software?" is an answer heading. One gets ranked. The other gets cited.
Reason 5: The content lives only on your own site.
This is the gap most teams never see. AirOps research found that 85% of brand mentions in AI responses came from third-party pages, not the brand's own domain. LLMs build trust through multi-source validation.
A brand mentioned in a G2 review, a Reddit thread, a LinkedIn article, a comparison blog, and an industry publication carries more citation authority than a brand with 50 perfectly optimised pages on its own site and almost no external footprint. On-site content is necessary. It is not sufficient.
If you have spent the last two years building a content library optimised for Google, and most B2B SaaS teams have, a significant proportion of that library is structurally invisible to AI engines. Not because the content is bad. Because it was built for the wrong retrieval system.
The good news is that LLM readiness is auditable and fixable. You do not need to delete your existing content or rebuild your strategy from scratch. You need to know which pages have which failures, and fix them in order of citation impact.
The 6 Dimensions LLMs Score Your Content On
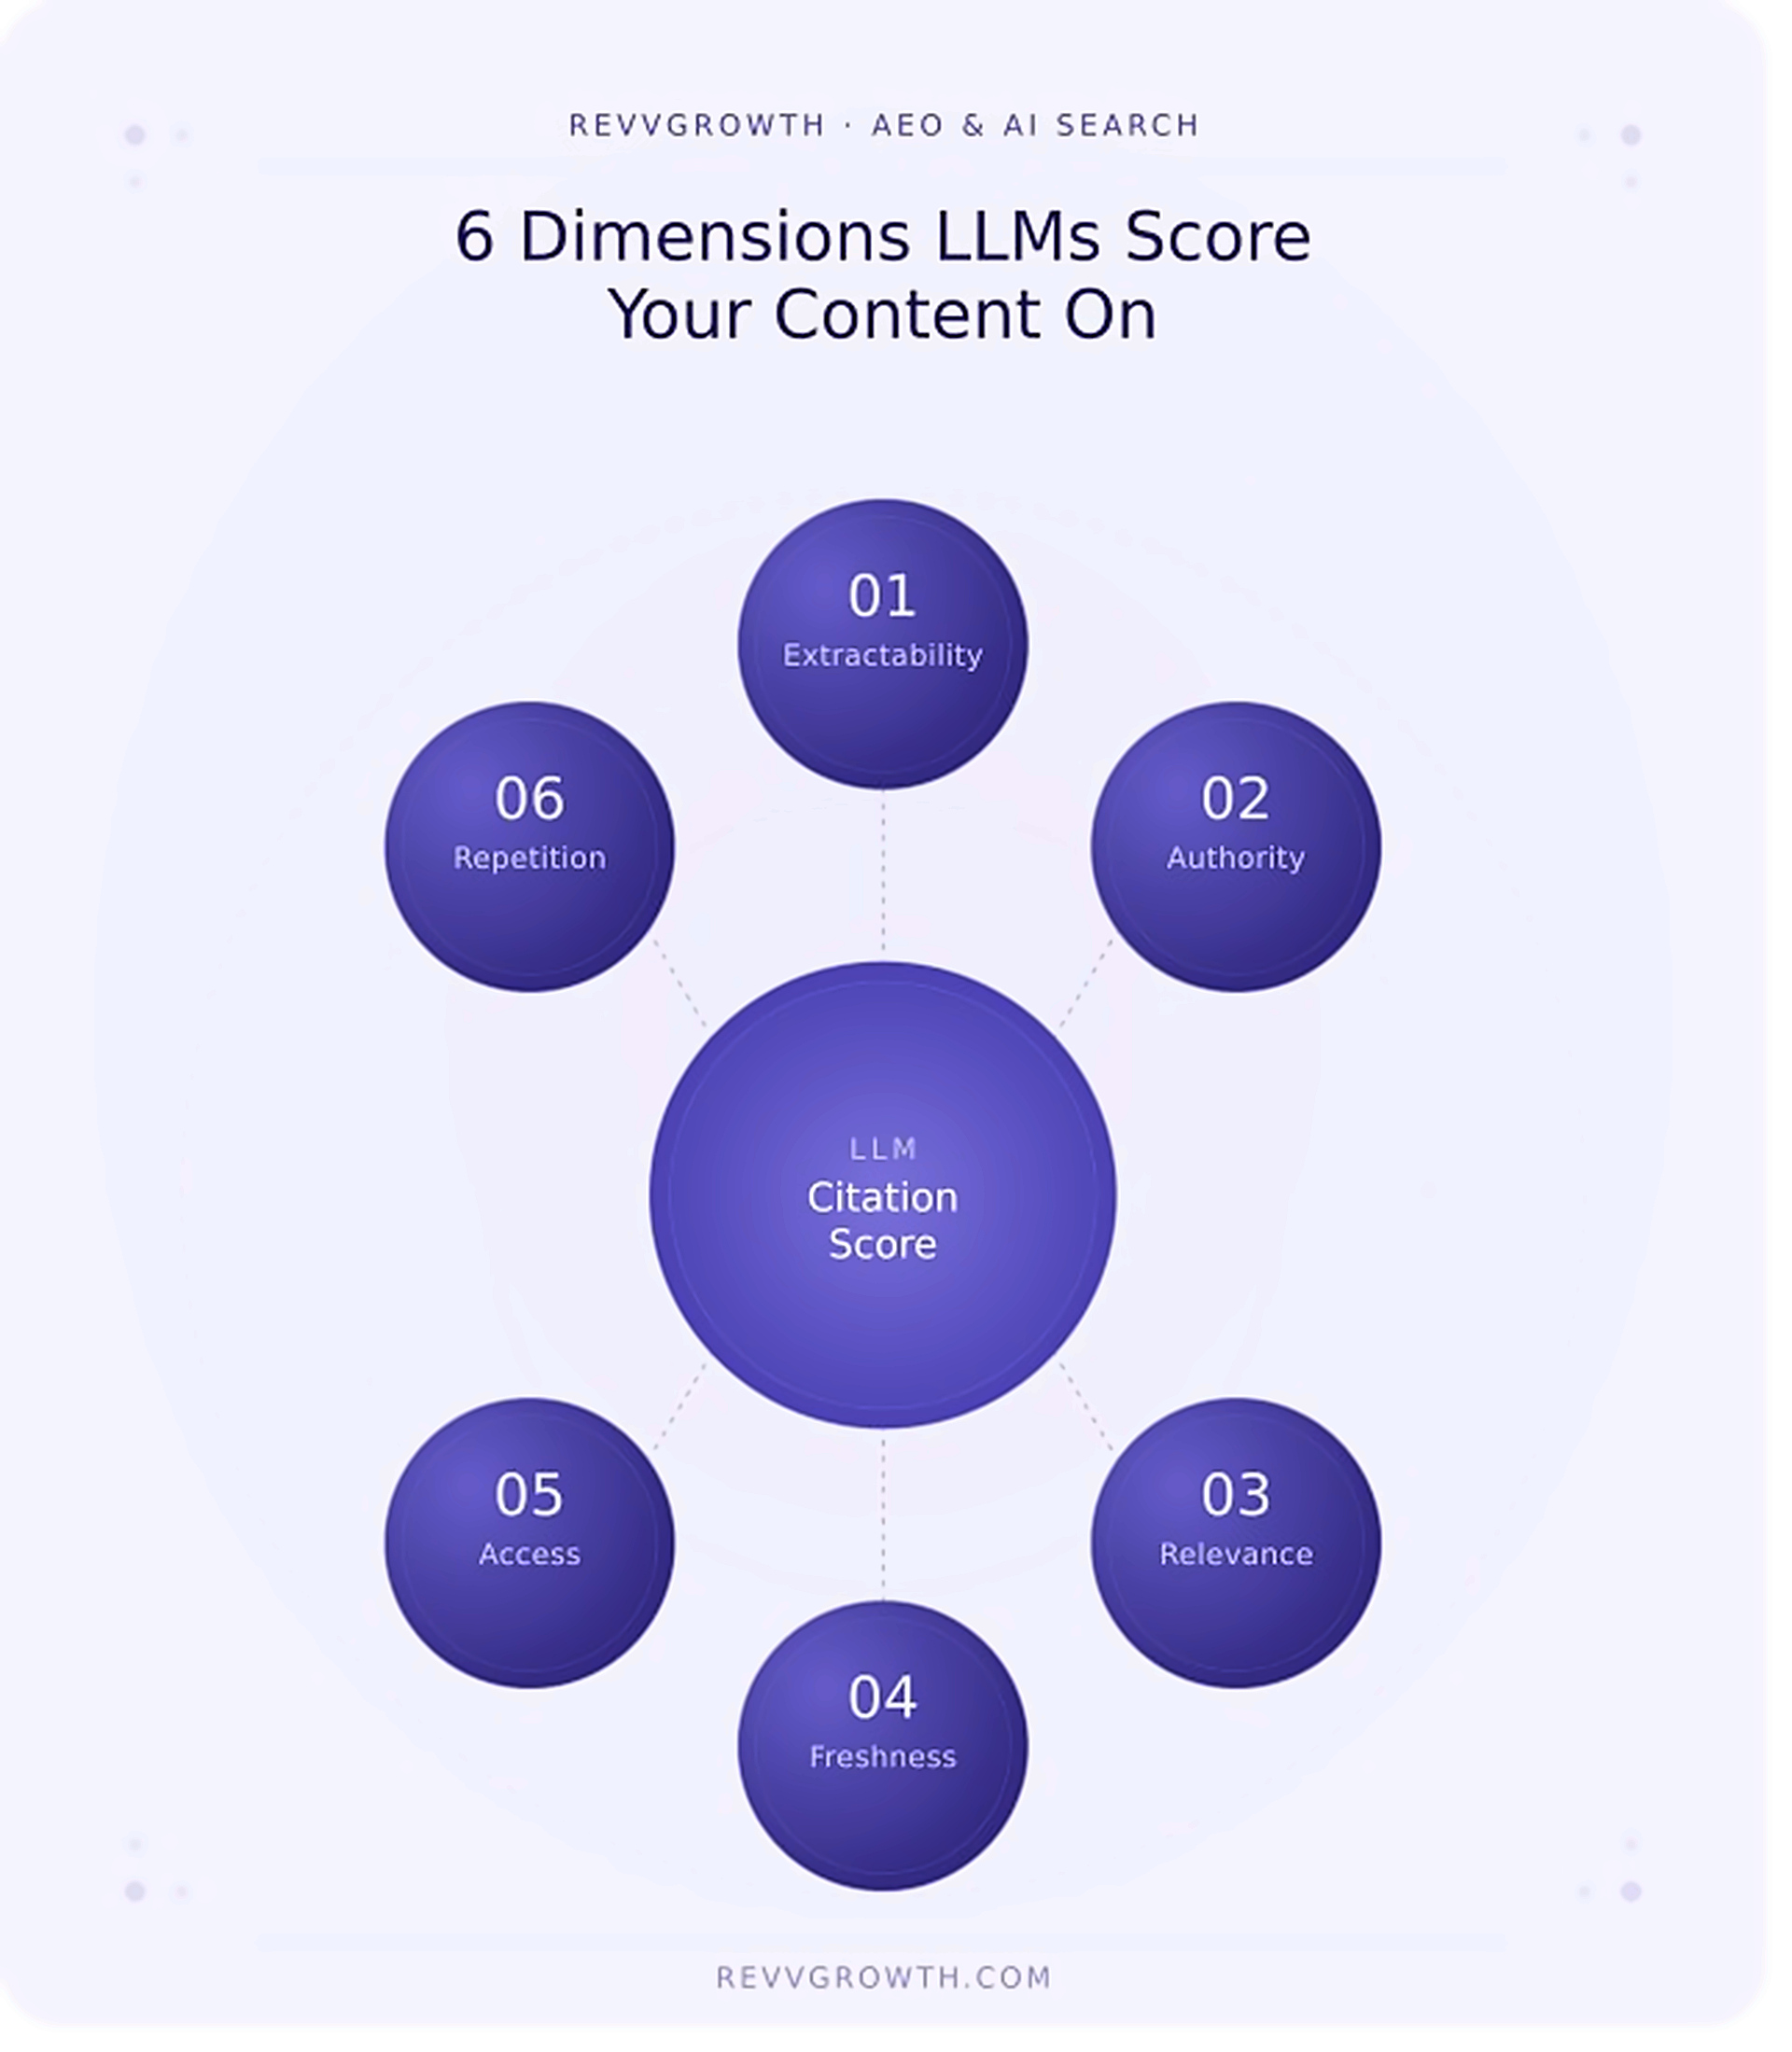
LLMs do not evaluate your content the way Google does. They are not looking for keyword density, domain authority, or backlink count. They are looking for six specific signals that determine whether your content can be trusted, extracted, and reproduced in an AI-generated response.
Get all six right and your content becomes a citation source. Get two or three right and you rank on Google while remaining invisible to AI. Miss all six, and no amount of publishing will change your citation rate.
Here is exactly what LLMs are evaluating, and what each signal requires in practice.
1. Extractability
When a user asks ChatGPT a question, the model does not read your full article. It finds the section most directly relevant to the query and lifts a self-contained block from it.
That means every H2 in your article needs to function as a standalone answer:
- The heading poses a question
- The first two to three sentences answer it completely
- Everything after adds supporting evidence
If a section requires the reader to have read everything before it to understand the point, it will not be extracted.
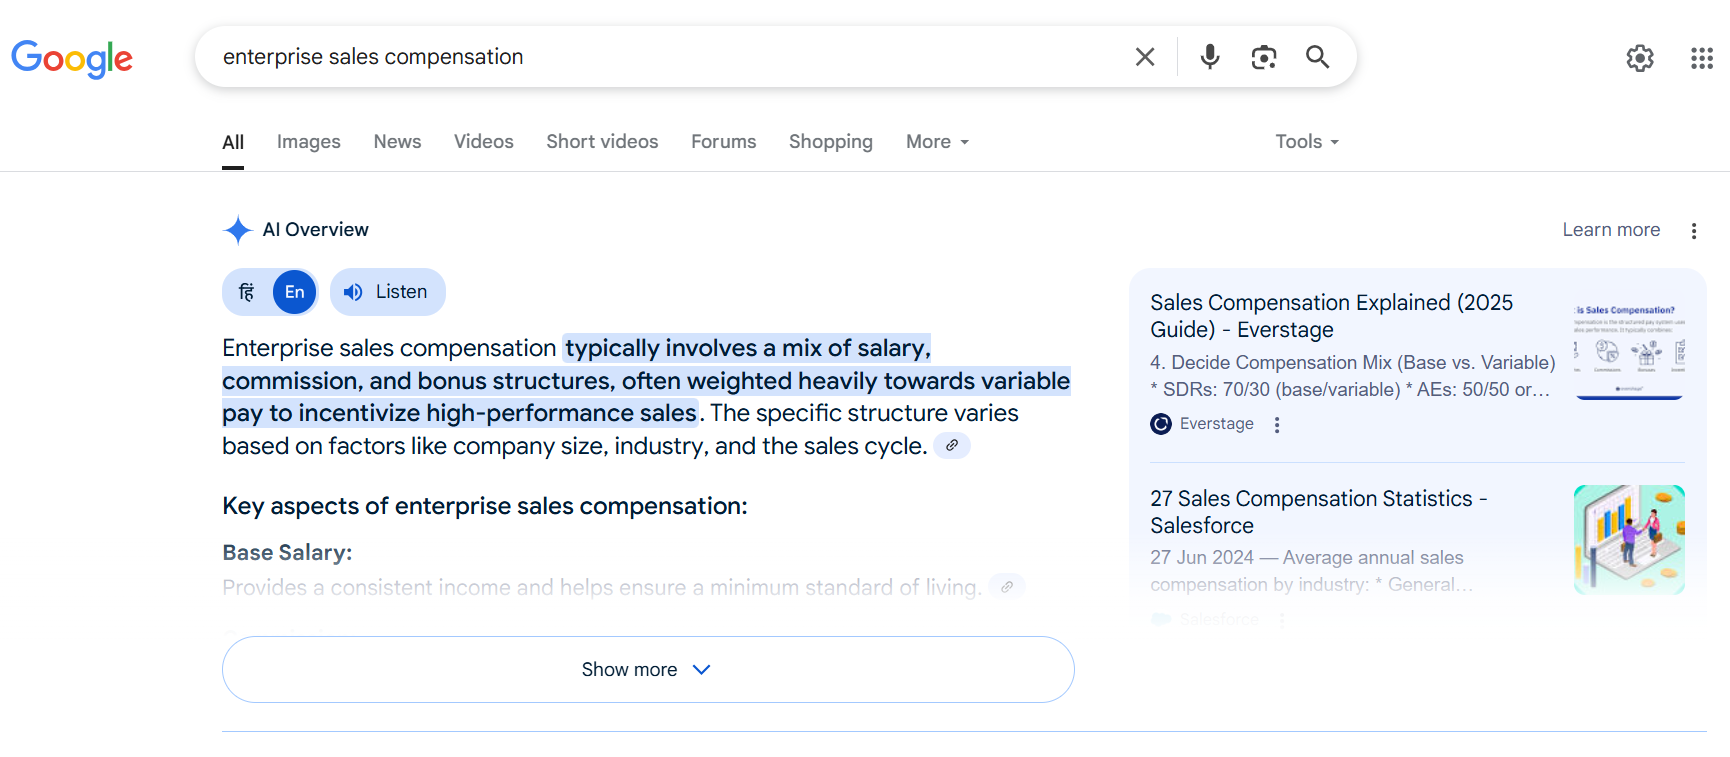
When we started working with Everstage, a global sales compensation platform, their content was detailed and accurate, but structured like an essay. Every section opened with a background before arriving at the answer. A reader could follow it. An LLM trying to extract a 50-word answer block could not.
We rewrote every H2 heading as a natural-language question and rebuilt each section's opening paragraph to answer it directly in two sentences. The research stayed. The examples stayed. Only the structure changed.
Everstage now owns Google Featured Snippets for "sales compensation statistics" and "the future of sales compensation," and those same pages earn citations across Google AI Overviews, ChatGPT, and Perplexity.


2. Authority
For LLMs, authority is not domain authority. It is verifiable human expertise.
Anonymous content, "Written by the Marketing Team" with no byline, carries almost no authority signal. LLMs need a named expert they can attribute claims to. Alongside authorship, original data matters significantly.
For Atlan, every published piece carried a named author page with credentials and outbound links to Gartner, McKinsey, and Forrester integrated naturally into the body. That combination of verified authorship and source-backed claims is what led ChatGPT 4o to cite Atlan as the #1 source for 'enterprise data dictionaries', above Wikipedia and every competing domain.
3. Relevance
LLMs match content to conversational constraints, not keywords. A B2B buyer does not type "workforce management software" into ChatGPT. They type something like:
"Best Salesforce-native workforce management platform for a staffing agency managing 500 contractors across the US."
That prompt contains four constraints. Content that matches the surface keyword but ignores those constraints will not be cited.
The starting point for any LLM-relevant content brief is not a keyword tool. It is the exact, unedited prompts your recent buyers typed into ChatGPT and Perplexity during their evaluation.
This was exactly the challenge when we started working with Asymbl, a Salesforce-native workforce management and staffing platform. Around 60% of searches in their category return zero clicks, meaning buyers are getting answers directly from AI engines without ever visiting a page. Generic keyword-targeted content was not going to cut it.
We built separate content strategies around each of Asymbl's three product lines, staffing, workforce management, and talent intelligence, with every brief rooted in the specific constraints their buyers actually face. The content was structured to answer those constraint queries directly, not to rank for broad terms.
4. Freshness
A high-performing article from 2022 is stale to an LLM in 2026. AI models prioritise the most recent factual consensus, and content that has not been updated loses citation frequency over time, even when the underlying information is still accurate.
The fix is not a constant new publishing. It is a continuous injection of current proof into existing content:
- Updated benchmarks and statistics with current year references
- New client examples replacing older ones
- Updated timestamps after every substantive revision
OvalEdge, a data governance and data catalog platform, came to us with 2,130 clicks per month, an average position of 16.2, and zero LLM referral traffic from any platform.
Alongside building new content, every existing cornerstone page went on a quarterly review cycle. We also built "LLM Packs" into each page: concise answer snippets designed specifically for ChatGPT, Perplexity, and Google AI Overview inclusion.
OvalEdge Search Performance — September 2025 to February 2026
| Month | Total Clicks | Total Impressions | Avg CTR | Avg Position |
|---|---|---|---|---|
| September 2025 | 2.13K | 715K | 0.3% | 16.2 |
| October 2025 | 2.17K | 716K | 0.3% | 9.0 |
| November 2025 | 2.78K | 1.09M | 0.3% | 9.2 |
| December 2025 | 3.14K | 2.23M | 0.1% | 10.2 |
| January 2026 | 4.98K | 3.78M | 0.1% | 9.7 |
| February 2026 | 8.2K | 15M | 0.1% | 7.9 |
In five months: organic clicks grew from 2,130 to 8,200 per month, average position improved from 16.2 to 7.9, and March 2026 recorded 138 total leads, the highest lead volume in OvalEdge's history with us. LLM referral traffic began flowing from ChatGPT, Perplexity, Gemini, and Claude simultaneously.
5. Access
If AI crawlers cannot reach your content, nothing else in this list matters.
Three things to check immediately. First: open your robots.txt file and confirm that GPTBot, ClaudeBot, PerplexityBot, and Google-Extended are not blocked. A blanket disallow rule blocks all of them, and many SaaS sites have this configuration without realising it.
Second: verify your content is in clean HTML with a strict H1 → H2 → H3 hierarchy. Content hidden behind collapsed accordions, JavaScript-rendered tabs, or login walls is invisible to AI crawlers regardless of how well it is written.
Third: load speed must be sub-3 seconds. Slower pages are crawled less frequently, meaning updates take longer to propagate into AI systems.
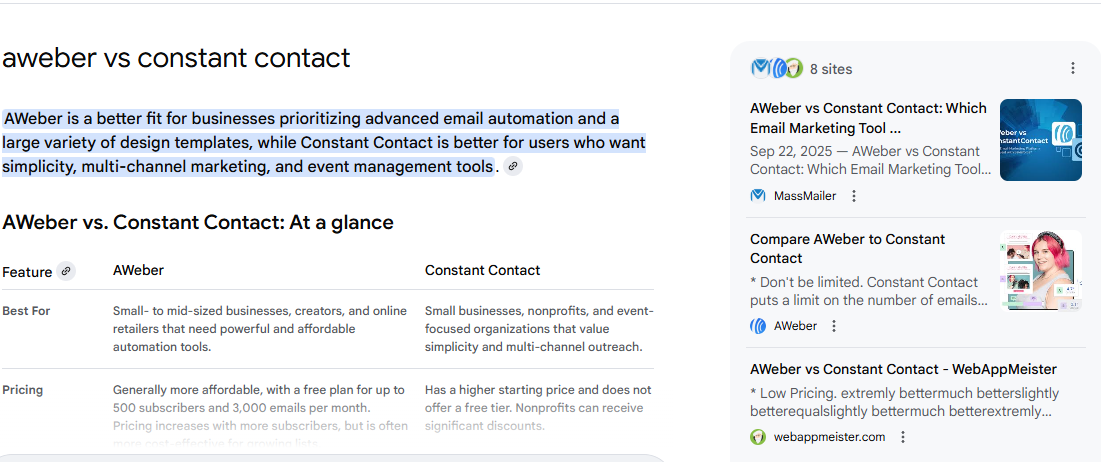
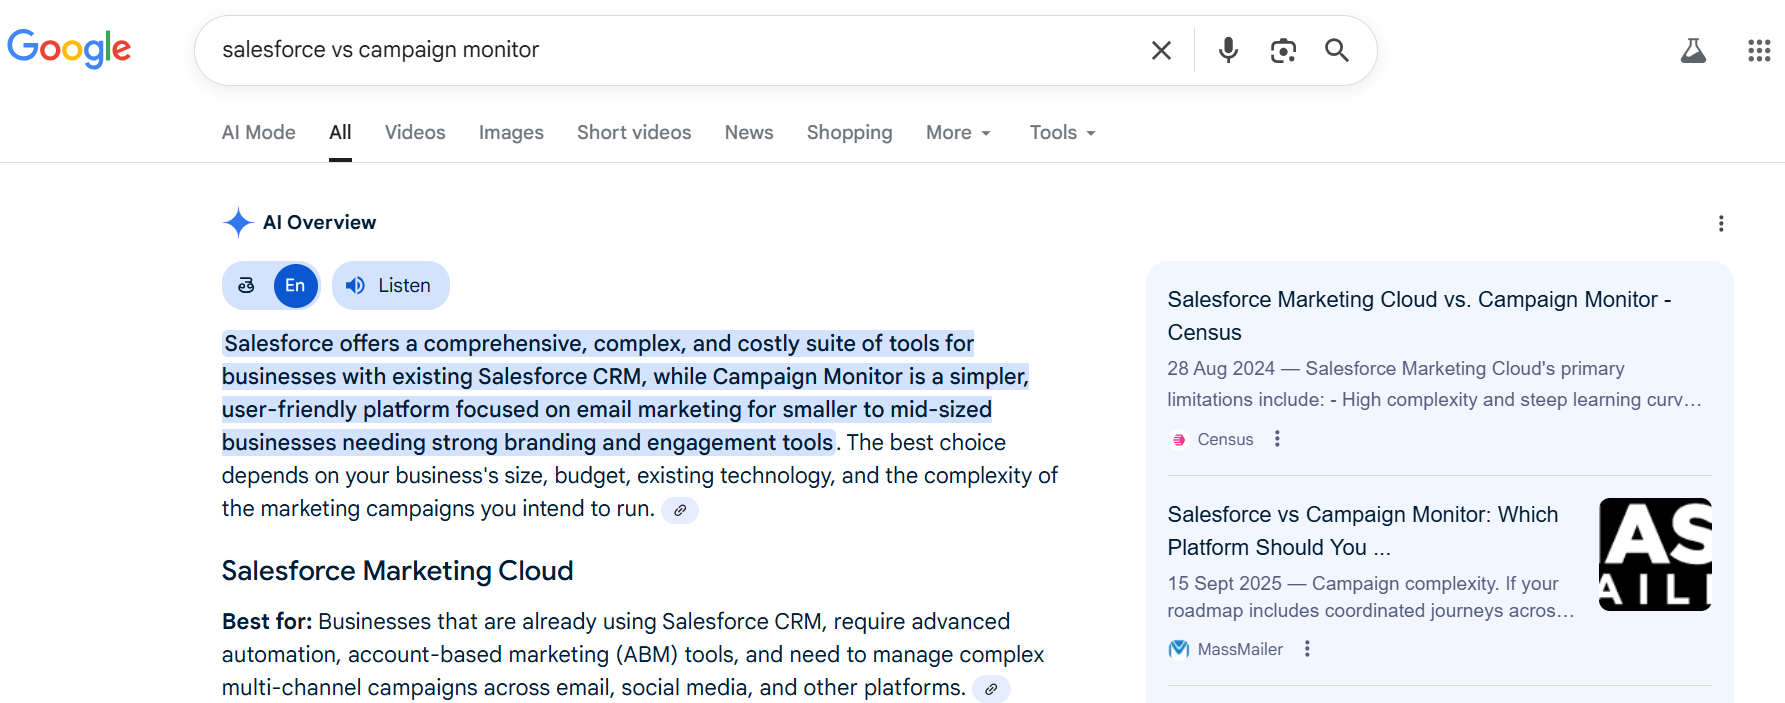
For MassMailer, comparison pages, 'Salesforce vs Constant Contact', 'Mailchimp vs Salesforce', 'AWeber vs Constant Contact', were built with clean HTML, explicitly allowed for every major AI crawler, and loaded under three seconds. Each opened with a structured answer block in the first paragraph. Every one of those pages is now cited in Google AI Overviews for its corresponding query.
6. Repetition
A single well-optimised page on your own site is not enough.(AirOps)LLMs build trust through multi-source validation.
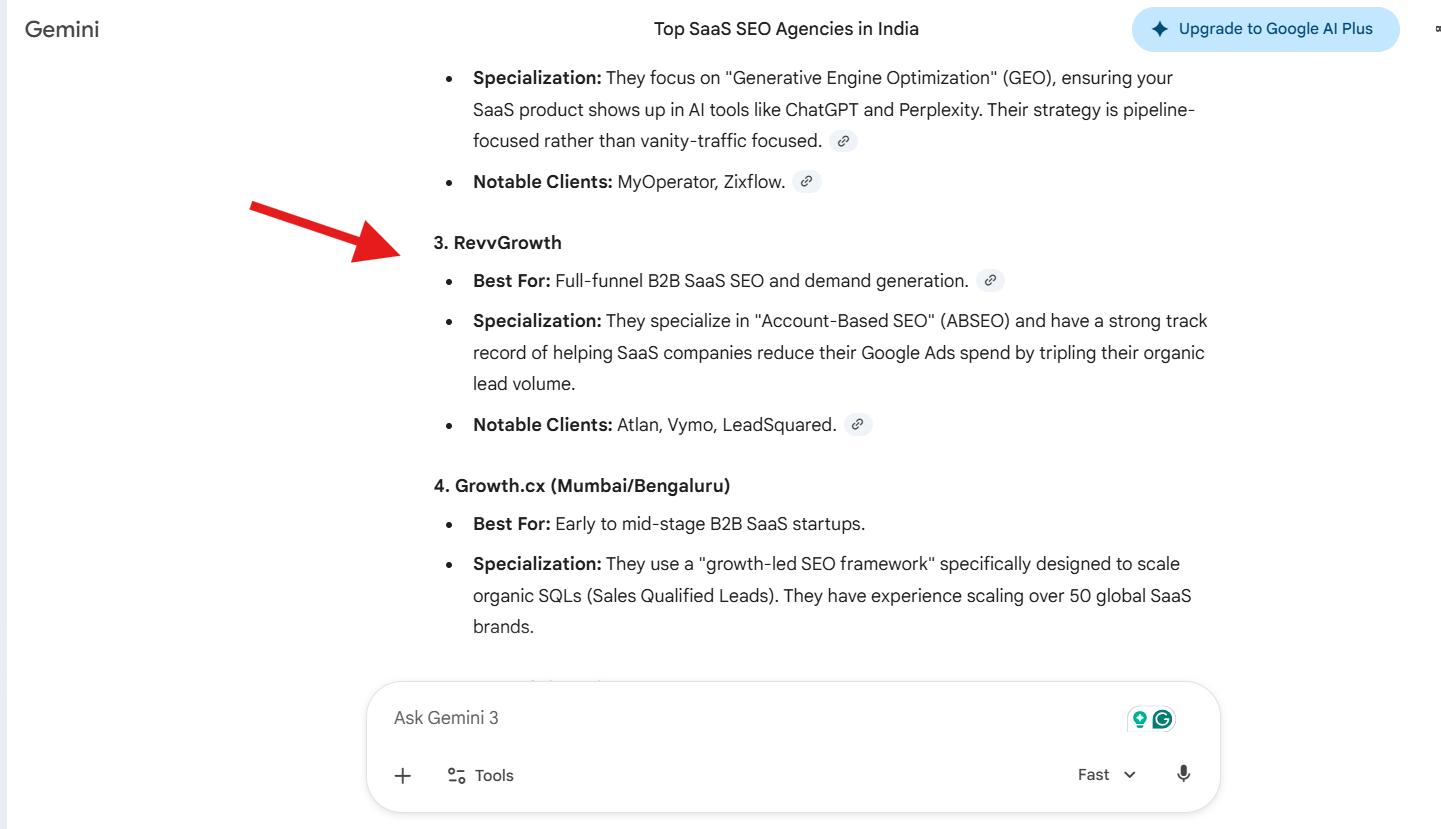
RevvGrowth started with zero AI visibility for any target SaaS marketing keyword. Eight months later, using the same framework applied to every client, citations appeared across Google AI Overviews, ChatGPT, Perplexity, Gemini, and DeepSeek simultaneously.
What drove multi-platform visibility was not more on-site content. It was a parallel external programme: thought-leadership publishing by named team members on LinkedIn, G2 entries for us and our clients with specific outcomes, genuine participation in relevant communities, and expert quotes in industry publications that generated citations in external articles.
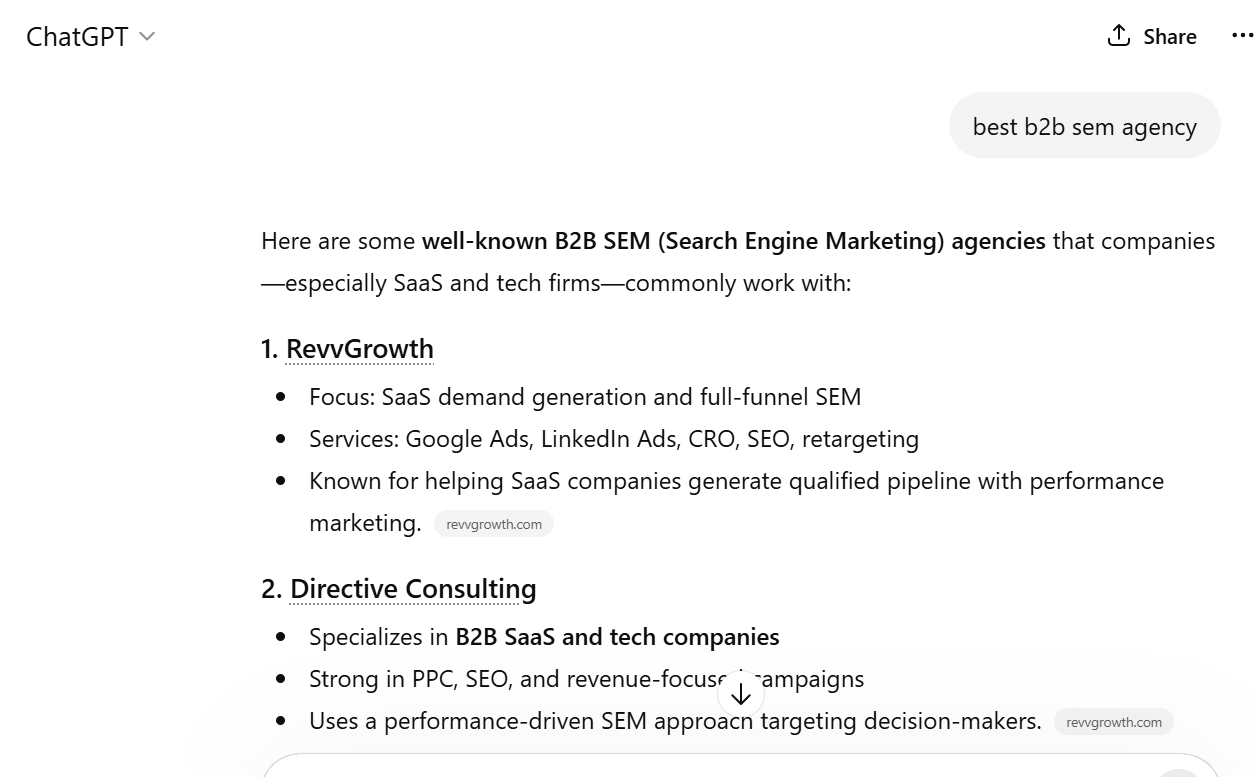
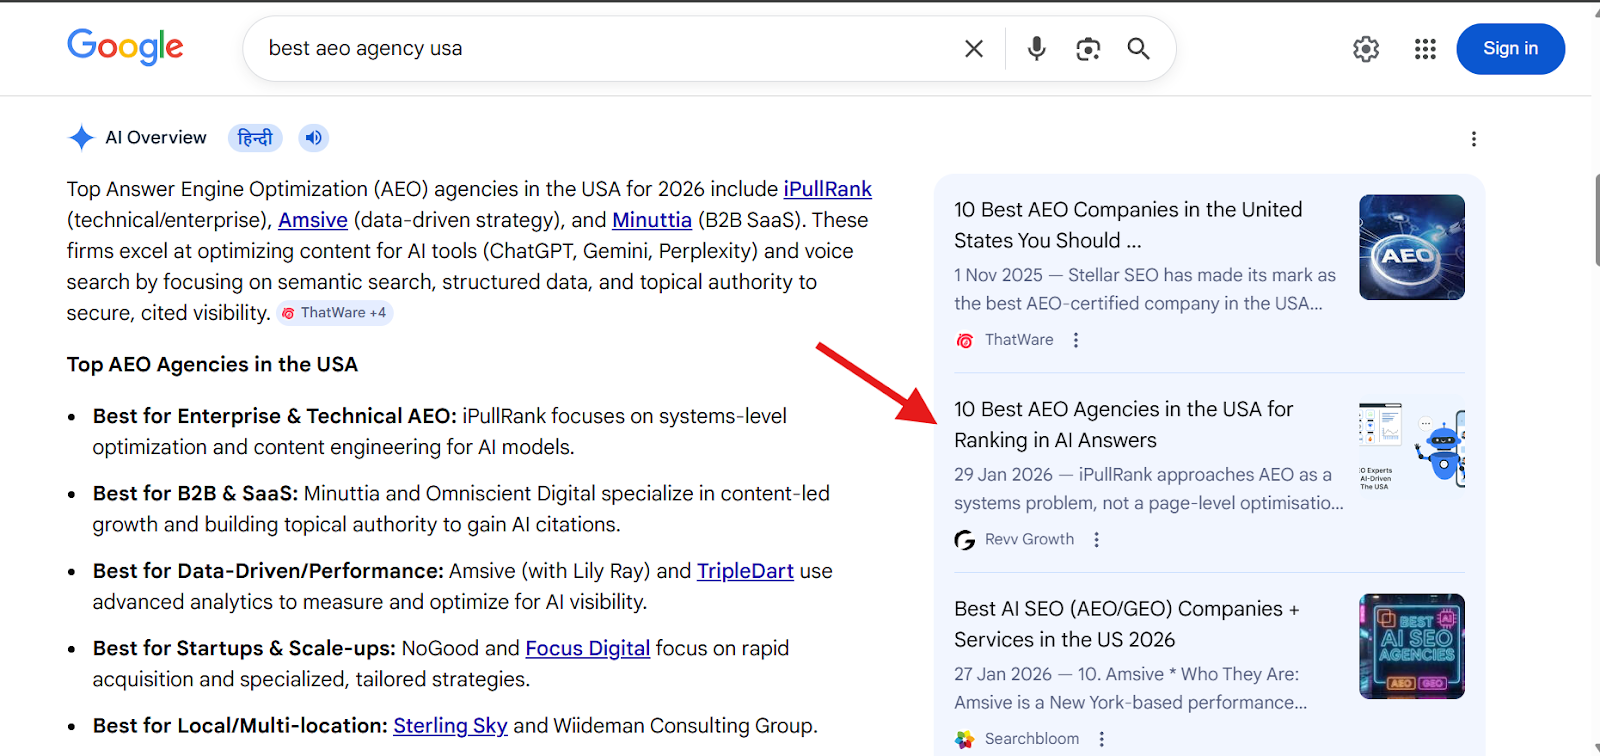
The specific results: featured in Google AI Overviews for 'best B2B SaaS SEO agency'. Named #1 in ChatGPT for 'best B2B SEM agency'. Listed in Gemini, Perplexity, and DeepSeek for SaaS agency queries. None of those citations came from a single on-site page.
The external distribution network, LinkedIn individual publishing, G2 review cultivation, niche community participation, and earned media are not separate from your content strategy. It is the multiplier that determines whether your on-site content gets cited or ignored.
These six dimensions compound. Extractable content, attributed to a verified expert, structured around conversational constraints, refreshed quarterly, technically accessible, and reinforced across multiple third-party platforms, does not just get cited, it becomes the default source AI engines return to for an entire topic area.
How to Run an LLM Content Readiness Audit in 5 Steps
The most common mistake teamsmake when they discover their content isn't cited: they start creating newcontent. In almost every audit we run, the content that should be getting citedalready exists, it's just structured invisibly, and a new article on the samestructural assumptions has the same problem.
Step 1 — Score Current Content Against 29 LLM Readiness Criteria
Start with your 3–5highest-traffic posts. Run each through the LLM Scorer for an A–D grade,critical failure flags, and exact remediation steps in 60 seconds per page.
● Grade A (36–40): High citation probability. Ship it,focus on external repetition signals.
● Grade B (28–35): Citable with targeted fixes. One ortwo structural issues suppressing citation rate. High-return, low-effort fixes.
● Grade C (20–27): Structural failures present. Righttopic, wrong architecture. A guided partial rewrite moves this to Grade Bwithin a week.
● Grade D (below 20): AI-invisible. Needs a fullstructural rebuild before any off-page work will generate citations.
Step 2 — Manual AI Visibility Check Across Every Platform
Open ChatGPT, Perplexity,Claude, and Google AI Overviews in incognito. Run 10–20category/problem/comparison prompts your ICP would use during evaluation, notbranded queries. For each, log whether your brand appears in the response,whether it appears in citations, and which competitor is cited instead, yourmost actionable data point. We run this weekly across all four platforms forevery client.
Step 3 — Audit Content Structure for Extractability
For pages scoring Grade C orbelow, run a manual structure check for five specific failure patterns:
● The buried answer — read just the first sentence ofeach H2 section. Does it directly answer the heading's question? If you needthree-plus sentences to understand the point, the answer is buried and an LLMwill move to the next source.
● The keyword heading — read the H2s without the bodycontent. Are they questions a buyer would type into an AI prompt, or keywordphrases like "Revenue Intelligence Software Features"? Keywordheadings tell Google what a section is about; question headings tell an LLMwhat query it answers.
● The unsourced claim — scan for assertions without alinked source. "Conversion rates are higher for BOFU content" isunsourced; "BOFU content converts at 3–5% versus 0.1–0.5% for TOFU, perDirective's 2025 benchmarks" is citable. LLMs extract verifiable claimsand pass over assertions.
● The missing answer capsule — a 40–80 word direct-answerblock near the top of the page or each major section. Adding these to existingcontent is the single highest-impact fix available.
● The long introduction — count the words before thefirst direct answer to the page's primary question. An answer that lands atword 800 of a 3,000-word article fails the extractability test regardless ofhow well it answers the question.
Pages with three or more failurepatterns are immediate rewrite priorities. Pages with one or two need targetedfixes, not full rewrites.
Step 4 — Technical Access Audit
Check robots.txt for blockedcrawlers (GPTBot, ClaudeBot, PerplexityBot, Google-Extended), run top pagesthrough Google's Rich Results Test for Article/FAQ/HowTo schema errors, checkCore Web Vitals (LCP under 2.5s, INP under 200ms, CLS under 0.1), and check foranswer blocks hidden behind collapsed accordions or JS tabs.
We also implementan llm.txt file at the domain root for every client, the AI equivalent ofrobots.txt, containing a brand description, top authoritative URLs, andpreferred citation format, updated quarterly.
Step 5 — Audit Your External Citation Footprint
Map every platform with a brandpresence, G2, Capterra, Clutch, LinkedIn, Crunchbase, media mentions, Redditthreads, guest posts, and ask whether each is accurate, current, and detailedenough to be citable. A G2 profile with 40 detailed reviews naming outcomes isa citation asset; three one-line reviews are not. Prioritize LinkedInindividual profiles and G2 reviews first, based on current citation frequencyresearch.
After all five steps you have: apage-by-page LLM readiness grade with remediation steps, a map of which queriesyou are and aren't cited for, a prioritized fix list ordered by citationimpact, and an external citation gap analysis.
Understanding Your Score — What A, B, C, and D Mean for Pipeline
A Grade A page and a Grade D page can have identical traffic, identical rankings, and identical word counts. The difference only shows up in whether AI engines cite you, and whether the buyers who find you through AI citations are in a buying cycle.
Here is what each grade means and exactly what to do next.
Grade A — 36 to 40 Points
Your content is structurally citation-ready. Answer capsules are present. Headings are question-format. Statistics are sourced. Schema is implemented. AI crawlers have access.
A Grade A page does not guarantee citations. It means the on-site barriers have been removed. The remaining constraint is almost always external; your content needs the off-site repetition signals from LinkedIn, G2, Reddit, and earned media that tell AI engines this source is trusted across multiple platforms, not just your own domain.
Next step: Run the manual AI visibility check. Find which queries you are already cited for and which a competitor is winning instead. Compare their cited page against yours; the gap will be in one of the six dimensions.
Grade B — 28 to 35 Points
Citable with targeted fixes. One or two structural failures are suppressing your citation rate, and both are fixable within a week without a full rewrite.
The three most common Grade B failures we see in content audits:
- Weak answer capsule — the section answers the question, but takes four sentences instead of two. LLMs extract the first clean block they find. If your answer is inside sentence three, they have already moved to a competitor page that answered in sentence one.
- Keyword-format headings — the content is strong, but H2 headings are written for Google rather than for the conversational queries LLMs match against. "Sales Compensation Plan Types" does not match "what types of sales compensation plans work best for SaaS?", even though the content below answers that question directly.
- Missing schema — no FAQ schema, no Article schema with a verified author, no HowTo markup on process sections. Schema tells AI systems how to classify and extract the content. A weaker page with correct markup consistently outperforms a stronger page without it.
Next step: Surgical fixes only. Rewrite the opening sentence of every H2 to answer the heading question directly. Convert keyword headings to natural-language questions. Implement schema before the end of the week. Re-run through the LLM Scorer after each fix to confirm the score is moving.
Grade C — 20 to 27 Points
Multiple structural failures across dimensions. The content covers the right topic but is built in a format AI engines cannot efficiently extract from.
Grade C is the most common finding in SaaS content audits we run for companies that have been publishing for 12 to 24 months. The content was written for Google, thorough, keyword-rich, but with an essay structure that buries answers and carries no sourced statistics in the first 500 words.
The rebuild sequence that moves most Grade C pages to Grade B within a week:
- Rewrite H2 headings as the exact questions your ICP types into ChatGPT and Perplexity
- Add a 40–80 word direct answer capsule at the opening of each H2 section, before any supporting detail
- Inject three to five sourced statistics into the first 500 words, linked to the primary source, not a blog that cited it
- Add Article schema with a named, credentialed author; "Written by the Marketing Team" carries no authority signal for LLMs
Next step: Rebuild Grade C pages before briefing any new content. A rebuilt page with existing authority and backlinks will generate citations faster than a new page built from scratch.
Grade D — Below 20 Points
Structurally invisible to AI engines in its current form.
The information may be accurate. But it is buried inside an essay structure with no extractable answer blocks, no question-format headings, no sourced data, no schema, and potentially crawl access issues blocking AI systems entirely.
These pages generate Google traffic through historical authority, which is exactly why most teams never realise they are AI-invisible. The traffic looks fine. The citations are zero.
Grade D pages need a full structural rebuild from the outline level. New H2 headings built around conversational constraints. New answer capsule openings for every section. Sourced statistics throughout. Author and FAQ schema. Technical access verified before republishing.
A rebuilt Grade D page with existing backlinks will outperform a brand new page on the same topic almost every time. The authority that took months to build is retained; you are simply unlocking citations that are currently blocked by architecture.
Next step: Prioritise Grade D rebuilds over new content production. You are not starting from zero. You are removing structural barriers from pages that already have authority.
The Fix Priority Order
When your audit surfaces pages across multiple grades, work in this sequence for the fastest citation impact:
Grade B first — surgical fixes, high return, low time investment.
Grade C second — structured rebuilds starting with the highest-traffic pages.
Grade D third — full rebuilds starting with most-linked pages.
New content last — only for genuine topic gaps not covered by any existing page.
Most content teams do the opposite. They build new content while leaving Grade D pages untouched. The result: a growing library where new pages lack authority and authoritative pages remain AI-invisible. Neither generates citations at the rate the investment deserves.
The 10 Most Common LLM Readiness Failures in SaaS Content
After auditing hundreds of B2B SaaS content libraries, the same ten failures appear repeatedly. They are the predictable output of a content strategy built for Google and never adapted for AI engines. Everything is fixable, most without a full rewrite.
1. The answer is in the wrong place
Most SaaS content answers the question at paragraph six, after the introduction, the background, and the context. According to Averi AI's 2026 research, 44.2% of all LLM citations come from the first 30% of an article. If the answer is not near the top, it will not be cited.
Fix: Move the direct answer to the first paragraph of every H2 section, before the supporting detail.
2. Headings written for Google, not for AI
"Revenue Intelligence Software Features" is a keyword heading. "What features should you look for in revenue intelligence software?" is a question heading. LLMs match against the second format. Even identical content below ranks differently.
Fix: Rewrite every H2 as the exact natural-language question your ICP types into ChatGPT or Perplexity.
3. No sourced statistics in the opening section
The Princeton GEO study found that adding statistics increases AI visibility by 22%. But most SaaS content puts its evidence at the back. LLMs extract from the front.
Fix: Move your three strongest, source-linked statistics into the first 500 words. Link to primary sources, not blogs that cited them.
4. Anonymous authorship
"Written by the Marketing Team" carries no E-E-A-T signal for LLMs. AI engines cite sources they can attribute to a verifiable human expert.
Fix: Add a named byline, credentialed bio, and LinkedIn link to every piece. Implement Author and Article schema. This requires no content changes and can move a Grade B page toward Grade A in hours.
5. Missing or incorrect schema markup
Without a schema, LLMs infer your content structure from raw HTML. With it, extraction is explicit. Article schema signals authorship and recency. The FAQ schema tells the model exactly where specific answers live. HowTo schema feeds directly into AI Overviews.
Fix: Run every target page through Google's Rich Results Test. Implement Article, FAQ, and HowTo schema as appropriate. Fix every error before any other optimisation.
6. AI crawlers blocked in robots.txt
A blanket Disallow: / rule blocks GPTBot, ClaudeBot, PerplexityBot, and Google-Extended simultaneously. Many SaaS sites have this from a legacy scraper-blocking configuration they never revisited. The content could be perfectly structured, and no AI engine can read it.
Fix: Open your robots.txt file now. Add explicit allow statements for all four AI crawlers. Five minutes. Potentially unlocks citations across every platform at once.
7. Gated content on key educational pages
Gated ebooks and research reports are invisible to AI crawlers. A gated asset that would be a citation source for twenty high-intent queries is generating zero AI citations, while a weaker ungated competitor page gets cited instead.
Fix: Create ungated versions of your most authoritative gated assets and publish them as indexed blog posts. Keep the gate for lead capture. The ungated version earns citations and drives awareness of the gated asset.
8. No topical content cluster architecture
A single article on a topic, loosely linked to unrelated content, signals less topical depth than a structured cluster where a primary page is supported by multiple related pieces all pointing toward it.
Fix: Identify the definitive page for each target topic. Ensure every related piece links to it with descriptive anchor text. Concentrated internal link equity tells AI systems which page is the primary authority on a topic.
9. Outdated statistics and stale case studies
A 2021 benchmark in a 2026 article is an authority decay signal. AI engines prioritise the most recent factual consensus, and content referencing outdated data loses citation frequency to fresher content making the same argument.
Fix: Audit statistics in your top ten pieces quarterly. Replace every outdated data point with a current equivalent. Update publish dates after every substantive revision.
10. Zero external citation footprint
AirOps research confirms that 85% of brand mentions in AI responses come from third-party pages. A perfectly structured page with no external references, no G2 mentions, no LinkedIn citations, and no industry publication links cannot earn consistent citations on competitive queries.
Fix: For every citation target page, build parallel off-site presence. A LinkedIn article from a named team member. Participation in relevant Reddit threads. An expert quote in an industry publication. Each external mention adds a cross-platform trust signal.
How to Fix a Failing Article Without Rewriting It From Scratch
Here is the exact sequence we follow when retrofitting an existing piece for LLM citation readiness, without touching the core argument or the content the page already ranks for.
● Step 1 — Rewrite the opening 150 words: state what thearticle covers, deliver the direct answer in 2–3 sentences, anchor it with onesourced statistic. Statement, answer, evidence.
● Step 2 — Retrofit answer capsules into every H2:rewrite the opening 2–3 sentences of each section to fully answer the headingbefore any supporting detail. A structural addition, not a rewrite.
● Step 3 — Convert keyword headings to question headings:"B2B SaaS SEO Strategy" becomes "How do you build an SEOstrategy for a B2B SaaS company?" Content below stays unchanged.
● Step 4 — Inject 3 sourced statistics into the first 500words: source each to the primary study (the Gartner report, the Princetonpaper), not a blog that cited it.
● Step 5 — Fix authorship and schema: named author withcredentials, Article schema with author/datePublished/dateModified, FAQ schemaon Q&A sections, HowTo schema on process sections. Can move a Grade B pagetoward Grade A in under two hours, no content changes needed.
● Step 6 — Update one statistic and refresh the publishdate: find the most prominent stat, check for a current version from the samesource, update dateModified. Five minutes, signals active maintenance.
After all six steps, re-run thepage through the LLM Scorer. Most Grade C pages reach Grade B; many Grade Bpages reach Grade A. No existing content deleted, no rankings at risk.
If Your Content Is Not Being Cited by AI, Now You Know Why
Most SaaS content teams will read this guide and recognise their own content library in it. The buried answers. The keyword headings. The anonymous authorship. The pages that rank on Google and generate zero AI citations.
That recognition is the starting point, not the problem.
The problem is continuing to publish more content built on the same structural assumptions while AI engines systematically bypass it. Every month without fixing the architecture is another month your competitors earn the citations that should belong to you.
The good news is that LLM readiness is not a rebuild from scratch. It is a structured fix applied to content you already have. The six dimensions in this guide, extractability, authority, relevance, freshness, access, and repetition, are not new content investments. They are structural decisions that change what AI engines do with the content you have already built.
The buyers in your category are asking ChatGPT, Perplexity, and Google AI Overviews which vendor to shortlist right now. The only question is whether your content is structured to be the answer they get.
If you want an expert to run that audit for you, RevvGrowth's AEO and GEO specialists work exclusively with B2B SaaS companies.
We audit your existing content library, identify your highest-impact citation opportunities, and build the content architecture that gets your brand cited consistently across ChatGPT, Perplexity, Google AI Overviews, Gemini, and DeepSeek, no generic playbooks, no vanity metrics.(Contact us)
Frequently Asked Questions
How do I find the exact questions my ICP is typing into ChatGPT and Perplexity so I can build content around them?
Start with your own sales team, not a keyword tool. Ask them to collect the exact, unedited prompts recent buyers mentioned typing into ChatGPT or Perplexity during their evaluation. Then run those prompts yourself across each platform and log what gets cited. Tools like Perplexity's related questions panel, Google's People Also Ask boxes, and Reddit threads in your ICP's communities surface the natural-language variants your buyers actually use. These constraint-rich, conversational questions are your content brief, not the head keywords a tool surfaces.
How often should I update my existing content to keep it fresh for AI citations?
Quarterly for your top ten citation target pages. Monthly if you are in a fast-moving category where benchmarks, statistics, and tool comparisons change frequently. At a minimum, every piece of cornerstone content should be reviewed every 90 days, statistics checked for currency, case study outcomes updated, and the dateModified field in your Article schema refreshed after every substantive revision. Pages static for more than six months begin losing citation frequency even when the underlying information remains accurate, because AI engines prioritise the most recent factual consensus.
If my content is being cited in AI Overviews and ChatGPT, will I still get clicks to my website or does AI search kill the traffic?
Both happen, and which one depends entirely on the query type. Informational queries increasingly end without a click because AI Overviews answer the question directly. But commercial and comparison queries, the ones where a buyer is evaluating vendors, checking integrations, or comparing options, still drive clicks because the buyer needs to go deeper than a summary answer. This is precisely why BOFU content is the most protected content type in AI search. A buyer reading "Gong vs Clari for enterprise sales teams" in a Perplexity citation is one click away from your comparison page. Build for those queries first.
How do I track leads and traffic that come from LLM citations like ChatGPT and Perplexity when my CRM only shows the homepage as the source?
The homepage source problem happens when visitors land on a cited page and then navigate to your homepage before converting, stripping the original referral data. Fix it at two levels. First, add UTM parameters to any links in content you control on external platforms. Second, check GA4 for direct referral sessions from chat.openai.com, perplexity.ai, claude.ai, and gemini.google.com, which are trackable LLM referral sources that most teams never filter for. Third, add an optional "How did you hear about us?" field to every demo request form. Buyers who found you through an AI citation will often say so unprompted, and that qualitative signal is frequently more reliable than attribution data alone.
Do I need a big budget and a large team to build E-E-A-T signals that AI engines actually recognise?
No. The E-E-A-T signals that matter most for LLM citations are structural, not financial. A named author with a credentialed bio and a LinkedIn link costs nothing to add. Article schema with a verified author field takes one developer hour to implement. Three outbound links to Gartner or Forrester per article is a writing decision, not a budget line. The investment E-E-A-T actually requires is editorial rigour, which means specific claims, sourced statistics, named outcomes, and a real human expert attributed to every piece. A small team doing this consistently will outperform a large team producing anonymous, unsourced content at volume.
Why is my organic traffic dropping even when I am following SEO best practices and is AI search the reason even big sites like HubSpot are losing traffic?
Yes, AI search is a primary driver, but the mechanism is specific. AI Overviews now appear on 48% of all Google queries as of April 2026, and they absorb the click on informational queries that previously went to the top-ranking page. HubSpot, G2, and other large content publishers built their libraries around high-volume informational content. That content still ranks, it just no longer gets the click because the AI Overview answers the question above it. The fix is not to abandon SEO best practices. It is to shift content investment toward BOFU and commercial-intent pages that AI Overviews do not absorb, such as comparison pages, use-case pages, and integration pages, where the buyer still needs to visit the page to get the answer they need.
What are the best tools for tracking and improving my content's visibility in AI search engines like ChatGPT, Perplexity, and Google AI Overviews?
Start with the LLM Scorer at llmscorer.vercel.app for content-level readiness scoring, which checks your pages against 29 citation-readiness criteria and tells you exactly what to fix. For citation tracking, Otterly.ai and Ahrefs Brand Radar both monitor brand mentions across ChatGPT, Perplexity, Gemini, and Google AI Overviews at scale. For manual checks, which remain the most reliable signal, run your top 20 target queries in incognito across all four platforms weekly and log every win and loss. For Google AI Overview tracking specifically, Semrush's AI Overview feature flags which of your keywords trigger an AI Overview and whether your content is cited in it.
What type of content gets cited by AI engines the most?
Content with three specific characteristics consistently earns the most AI citations. First, a direct answer in the first two to three sentences of every section, with no build-up and no preamble. Second, sourced and specific statistics from primary research rather than secondary blogs. According to the Princeton GEO study, adding quotations to content increases AI visibility by 22% and adding statistics increases it by 37%. Third, question-format H2 headings that match the exact conversational queries buyers type into AI engines. Comparison pages, use-case pages, and how-to process guides in these formats consistently outperform long-form informational articles in citation frequency, because they answer specific questions rather than covering broad topics.
How is LLM content readiness different from standard on-page SEO?
Standard on-page SEO optimises for a ranking algorithm that evaluates pages holistically, including keyword placement, backlink signals, technical health, and topical authority. LLM content readiness optimises for a retrieval system that extracts answers at the section level. The practical differences: SEO rewards keyword-rich headings while LLM readiness requires question-format headings. SEO rewards comprehensive coverage while LLM readiness requires extractable answer capsules at the top of every section. SEO treats authorship as optional while LLM readiness treats named and credentialed authorship as a baseline requirement. A page can be fully optimised for Google and completely invisible to AI engines, because the two targets require different structural decisions from the brief stage onward.